Recently I came across a situation where someone was running a query, basically copying data from one table to another.
The query was simple enough. Basically it was using a fast forward cursor, copying one record from one table into another table. Using SCOPE_IDENTITY, the query retrieved the identity value of the newly inserted record and then inserted another record in a child table, using newly generated identity key. There were several hundred millions of records in the table from which the data was being moved to a new table. Whether this could have been done another way is not the topic for today.
In this particular instance, the query was running in Query Analyzer and it will run for a while, but then will throw an out of memory exception. Since the query didn't track what records were inserted already in the new table before out of memory exception was thrown, the developer truncated the new table and started all over again, only to hit the same issue again.
The reason query was throwing out of memory exception was because the query didn't have SET NOCOUNT ON clause at the beginning. As a result, the query was outputting messages for each statement in this query, not only resulting in memory consumption but also degrading the performance and increasing the network traffic. SET NOCOUNT ON basically prevents the sending of DONE_IN_PROC messages to the client.
The query need not run in a loop like above or in query analyzer to make use of SET NOCOUNT ON. If you don't need messages being returned from the SQL Server or aren't capturing them, be sure to add this clause to your stored procedures.
Thank you.
Friday, July 6, 2012


Monday, July 2, 2012
SQL Server - Degree of Parallelism
In SQL Server 2008, Microsoft introduced a concept called max degree of parallelism. Max degree of parallelism allows the engine to take advantage of all the available processors on the server up to 64 processors to execute a single SQL statement. By default, SQL Server is configured to use all available processors, however, there may be instances where you want to limit the number of processors a query should use. For example, you may have a low priority SQL agent job running in the background and you want to limit it to only use one processor. You can set max degree of parallelism to 1.
The query below will only use up to 2 processors for parallel operation regardless of the number of processors available.
To set the option for SQL Server to always use up to X number of processors, you can use SP_Configure.
For example, the following query forces SQL engine to only use 4 processors.
Default "Max Degree of Parallelism" option is 0, which means use all available processors up to 64.
Thank you.
The query below will only use up to 2 processors for parallel operation regardless of the number of processors available.
USE AdventureWorks
GO
SELECT ProductID, OrderQty, SUM(LineTotal) As Total
FROM Sales.SalesOrderDetail
WHERE UnitPrice < $10.00
GROUP BY ProductID, OrderQty
ORDER BY ProductID, OrderQty
OPTION (MAXDOP 2)
GO
To set the option for SQL Server to always use up to X number of processors, you can use SP_Configure.
For example, the following query forces SQL engine to only use 4 processors.
USE Master
GO
SP_Configure 'Show Advanced Options', 1
GO
RECONFIGURE
GO
SP_Configure 'Max Degree of Parallelism', 4
GO
RECONFIGURE
GO
Default "Max Degree of Parallelism" option is 0, which means use all available processors up to 64.
Thank you.
Thursday, June 28, 2012
SQL 2012 (Denali) - Paged Query Results
Anyone who has been developing web based or even windows based systems must have gone through the pain of fetching few records at a time from the database.
Suppose your grid view displays 20 records per page. Your option was to either fetch all records on every grid page and every time user changed the page, make another trip and fetch all records again (or save everything in view state / session) - not an ideal solution. Your other option was to get a list of all primary / identity keys and then pass a set of keys to the query to only fetch the records that pertain to those keys. For example, get keys 1 - 20 on page 1, 21 - 40 on page 2 and so on. But what if someone deleted, say record #22 from the database? Another implementation I have seen is where code passes the page number and number of records that each page displays and the stored procedure applies some complex logic to figure out what records to send back. Using ROW_NUMBER() and CTE was a better alternative, but it was still not very intuitive and easy to use.
SQL 2012 introduced Ad-Hoc paging, allowing you to only fetch the appropriate number of records. Two clauses "OFFSET" and "FETCH" make this happen. Fetch clause fetches only the next X number of records you want to retrieve and OFFSET tells the query to start from the record # Y.
For example, suppose I have 1000 users in my table and my grid only shows 10 users at a time. I can pass two parameters to my query and it will return me correct 10 users every time.
You can even use expressions in OFFSET and FETCH Clause such as @Offset - 1 and @RecordsPerPage - 1.
You don't have to have paging in grid view to make use of this. Often time you may need X number of records from the middle of the result set, where this could be very helpful.
For Fetch to return expected set of records every time, you obviously have to make sure other routines aren't deleting / inserting records in the middle which may cause an unexpected behavior. For example, let's say your OFFSET clause tells the query to start at record # 11, but what if someone deleted a record say at #5 after you retrieved first 10 records? Record number 11 is now what would have been record number 12, thus your query will not return you one record (original record at #11 but now at # 10).
Thank you.
Suppose your grid view displays 20 records per page. Your option was to either fetch all records on every grid page and every time user changed the page, make another trip and fetch all records again (or save everything in view state / session) - not an ideal solution. Your other option was to get a list of all primary / identity keys and then pass a set of keys to the query to only fetch the records that pertain to those keys. For example, get keys 1 - 20 on page 1, 21 - 40 on page 2 and so on. But what if someone deleted, say record #22 from the database? Another implementation I have seen is where code passes the page number and number of records that each page displays and the stored procedure applies some complex logic to figure out what records to send back. Using ROW_NUMBER() and CTE was a better alternative, but it was still not very intuitive and easy to use.
SQL 2012 introduced Ad-Hoc paging, allowing you to only fetch the appropriate number of records. Two clauses "OFFSET" and "FETCH" make this happen. Fetch clause fetches only the next X number of records you want to retrieve and OFFSET tells the query to start from the record # Y.
For example, suppose I have 1000 users in my table and my grid only shows 10 users at a time. I can pass two parameters to my query and it will return me correct 10 users every time.
CREATE PROCEDURE getPagedRecords

@Page INT = 1,
@RecordsPerPage INT=10

AS
BEGIN
    DECLARE @Offset INT
    SET @OffSet = Page * @RecordsPerPage

    SELECT
        UserID,
        FirstName,
        LastName,
        EmailAddress
    FROM Users
    ORDER BY UserID
    OFFSET @Offset ROWS
    FETCH NEXT @RecordsPerPage ROWS ONLY;
END
You can even use expressions in OFFSET and FETCH Clause such as @Offset - 1 and @RecordsPerPage - 1.
You don't have to have paging in grid view to make use of this. Often time you may need X number of records from the middle of the result set, where this could be very helpful.
For Fetch to return expected set of records every time, you obviously have to make sure other routines aren't deleting / inserting records in the middle which may cause an unexpected behavior. For example, let's say your OFFSET clause tells the query to start at record # 11, but what if someone deleted a record say at #5 after you retrieved first 10 records? Record number 11 is now what would have been record number 12, thus your query will not return you one record (original record at #11 but now at # 10).
Thank you.
Monday, June 25, 2012
SQL Server 2012 (Denali) Sequence Object
In addition to several enhancements in SQL 2012 - (some of which we will cover in subsequent posts), one of the key feature introduced is a sequence object.
Think of sequence object as an identity field on steroids. An identity field allows you to generate an auto number incremented by whatever increment value you desire (default is one) every time a record is inserted in a table. But, identity field is specific to a table, just like any other field defined in a given table. Additionally, if you delete the previous record, the identity value associated with the deleted record is lost forever until you do something to reseed it. Once the identity field hits the maximum limit (depends on the data type of this field), you've got a problem and you must reseed the table to start over or do something else.
Sequence object can help you mitigate this problem somewhat. First, let's briefly review this object. The Sequence object is created independently of a table and can be used across multiple tables.
For example - I can create a sequence object called OrderNumber, have it start with 1000 and increment by 1.
Now this sequence object is available to be used in multiple tables.
Let's imagine I have a table called OrderHeader and OrderDetails in my database.
Instead of inserting record in OrderHeader and then using SCOPE_IDENTITY() or some other method to get the OrderNumber before inserting the record in OrderDetails table, I can use the sequence "OrderNumber" I created above and insert the same number in both tables.
NEXT VALUE FOR gives you the next available sequence number. Every time you call it, the object will return the next available number, so if you want to use the same number in multiple tables, you have to be careful to call it only once.
Another nice feature of the sequence object is that you can reset it. As in my example above, if you are deleting previous records, then you know your previous order numbers are becoming available. After you have reached fairly large number, you can start over. You obviously have to ensure you don't reset sequence and then try to use the new sequence number which may already exist in your table.
There are two ways to reset the sequence (dropping and recreating is a third way). One, by defining a maximum value for the sequence when you created it and another by altering an already created sequence.
The OrderNumber sequence in above example will recycle once it hits 1000000.
As you can see, Sequence object is quite flexible and if used judiciously can serve as a nice tool. Sys objects provide additional methods to get the range of values or to find out the current sequence value etc.
Thank you.
Think of sequence object as an identity field on steroids. An identity field allows you to generate an auto number incremented by whatever increment value you desire (default is one) every time a record is inserted in a table. But, identity field is specific to a table, just like any other field defined in a given table. Additionally, if you delete the previous record, the identity value associated with the deleted record is lost forever until you do something to reseed it. Once the identity field hits the maximum limit (depends on the data type of this field), you've got a problem and you must reseed the table to start over or do something else.
Sequence object can help you mitigate this problem somewhat. First, let's briefly review this object. The Sequence object is created independently of a table and can be used across multiple tables.
For example - I can create a sequence object called OrderNumber, have it start with 1000 and increment by 1.
Create SEQUENCE [dbo].[OrderNumber]
as int
START WITH 1000
INCREMENT BY 1;
Now this sequence object is available to be used in multiple tables.
Let's imagine I have a table called OrderHeader and OrderDetails in my database.
CREATE TABLE [dbo].[OrderHeader](
    [OrderNumber] [int] NOT NULL,
    [OrderDate] [smalldatetime] NOT NULL,
    [StatusID] [int] NOT NULL
) ON [PRIMARY]
CREATE TABLE [dbo].[OrderDetails](
    [OrderNumber] [int] NOT NULL,
    [ItemID] [int] NOT NULL,
    [Quantity] [int] NOT NULL,
    [Price] [money] NOT NULL
) ON [PRIMARY]
Instead of inserting record in OrderHeader and then using SCOPE_IDENTITY() or some other method to get the OrderNumber before inserting the record in OrderDetails table, I can use the sequence "OrderNumber" I created above and insert the same number in both tables.
DECLARE @OrderNumber INT
SELECT @OrderNumber = NEXT VALUE FOR dbo.OrderNumber
INSERT INTO Orders(OrderNumber,OrderDate,StatusID)
VALUE (@OrderNumber,GetDate(),1)

INSERT INTO OrderDetails(OrderNumber,ItemID,Quantity,Price)
VALUE (@OrderNumber,100,10,'2.25')
NEXT VALUE FOR gives you the next available sequence number. Every time you call it, the object will return the next available number, so if you want to use the same number in multiple tables, you have to be careful to call it only once.
Another nice feature of the sequence object is that you can reset it. As in my example above, if you are deleting previous records, then you know your previous order numbers are becoming available. After you have reached fairly large number, you can start over. You obviously have to ensure you don't reset sequence and then try to use the new sequence number which may already exist in your table.
There are two ways to reset the sequence (dropping and recreating is a third way). One, by defining a maximum value for the sequence when you created it and another by altering an already created sequence.
Create SEQUENCE [dbo].[OrderNumber]
as INT
START WITH 1000
INCREMENT BY 1
MINVALUE  1000
MAXVALUE  1000000
CYCLE
The OrderNumber sequence in above example will recycle once it hits 1000000.
ALTER SEQUENCE OrderNumber
 RESTART WITH 1000 ;
As you can see, Sequence object is quite flexible and if used judiciously can serve as a nice tool. Sys objects provide additional methods to get the range of values or to find out the current sequence value etc.
Thank you.
Friday, June 22, 2012
SQL Server - Checking Where an Object is used
As databases grow in size and complexity, often there are dead objects that are left behind. By dead, I mean these objects are no longer being used, but everyone is afraid to drop them for fear of breaking something. SQL Server provides a simple way to determine where an object is being used so you can decide whether it is needed or not. SQL Server will tell you whether your object is being used in a function or stored procedure or a view etc. it obviously can't tell you whether another application is referencing such an object. So, before you delete an object if the query below doesn't return anything, further research may be necessary.
The script below will accept the object name and list all other objects that are using/referencing this object.
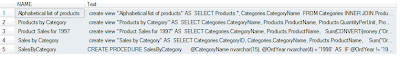
For example, if I run the above script in Northwind database to check where "Categories" table is being used, I get the following result.
Happy Coding!
Thank you.
The script below will accept the object name and list all other objects that are using/referencing this object.
    --Declare a variable or alternatively you could create
    --a stored procedure and pass this as a parameter.
    DECLARE @objectName nvarchar(4000)
    --name of your object.
   SET @ObjectName = 'MyObject'
   SELECT
        S.NAME,
        C.Text

    FROM SysObjects S
    INNER JOIN SysComments C
        ON S.ID = C.ID
    WHERE
        C.Text LIKE '%' + @ObjectName + '%'
For example, if I run the above script in Northwind database to check where "Categories" table is being used, I get the following result.

Happy Coding!
Thank you.
Saturday, June 16, 2012
SQL Server Pivot Function
In previous post we discussed exporting data from SQL Server into an excel file and how you can pivot the data etc. Pivoting is basically a way for you to convert rows into columns. Starting with 2005, SQL Server introduced PIVOT function which allows you to retrieve columns in tabular format. PIVOT function doesn't work on certain data types such as XML.
In the past, suppose you wanted to group employees by the city they reside in. You can use Group By clause to get the count of the number of employees by city, but such a query will result in each city as one row and you will have to do something extra to convert them into columns. The query below will return the number of employees that reside in three cities with the count for each city appearing in one row.
The result will look like this
Now the result will look like this
You may be wondering about missing WHERE clause. Basically FOR City IN () under PIVOT function takes care of filtering your data based on your criteria. This query works but the nested query still returns all rows. You can add a WHERE clause in your nested query to only return rows that satisfy your criteria. Above query can be rewritten as follows...
PIVOT is a useful function but not very intuitive, as you can see above, it takes a minute to make sense of it. Question for you guys - have you used PIVOT function before and if so, how did you use it?
Thank you.
In the past, suppose you wanted to group employees by the city they reside in. You can use Group By clause to get the count of the number of employees by city, but such a query will result in each city as one row and you will have to do something extra to convert them into columns. The query below will return the number of employees that reside in three cities with the count for each city appearing in one row.
USE AdventureWorks
GO

SELECT City,COUNT(*) AS [Count] FROM HumanResources.vEmployee
WHERE City IN ('Monroe','Redmond','Seattle')
Group By City
The result will look like this
| City | Count |
| Monroe | 14 |
| Redmond | 21 |
| Seattle | 44 |
Suppose you want to pivot this data so that each city appears as a column. You can modify the above query and use PIVOT function.
Use AdventureWorks
GO
SELECT [Monroe],[Redmond],[Seattle]
FROM
(
    SELECT E.City FROM HumanResources.VEmployee E
) C
PIVOT
(
 COUNT (City)
 FOR City
 IN ([Monroe],[Redmond],[Seattle])
 ) AS PivotTable;
Now the result will look like this
| Monroe | Redmond | Seattle |
| 14 | 21 | 44 |
You may be wondering about missing WHERE clause. Basically FOR City IN () under PIVOT function takes care of filtering your data based on your criteria. This query works but the nested query still returns all rows. You can add a WHERE clause in your nested query to only return rows that satisfy your criteria. Above query can be rewritten as follows...
Use AdventureWorks
GO
SELECT [Monroe],[Redmond],[Seattle]
FROM
(
    SELECT E.City FROM HumanResources.VEmployee E
    WHERE City IN ('Monroe','Redmond','Seattle')
) C
PIVOT
(
 COUNT (City)
 FOR City
 IN ([Monroe],[Redmond],[Seattle])
 ) AS PivotTable;
PIVOT is a useful function but not very intuitive, as you can see above, it takes a minute to make sense of it. Question for you guys - have you used PIVOT function before and if so, how did you use it?
Thank you.
Subscribe to:
Posts (Atom)